Who is behind open10k.com
A few years ago I was asked to teach an accounting analytics course. I stumbled on the Financial Statement Data Sets from the SEC and was awestruck at how powerful the dataset was. It bothered me that the SEC gives the data away — free to all — and yet having access to trends in 10-K data still required an expensive subscription. After working on the data for two or three years, I used AI to expand on my queries and to build the code that assembles them into Excel files.
So this is a research project, not a product. The data is free because the filings are public and the work of cleaning them up should not have to be repeated by everyone who needs it. Made with Malloy — a new data language.
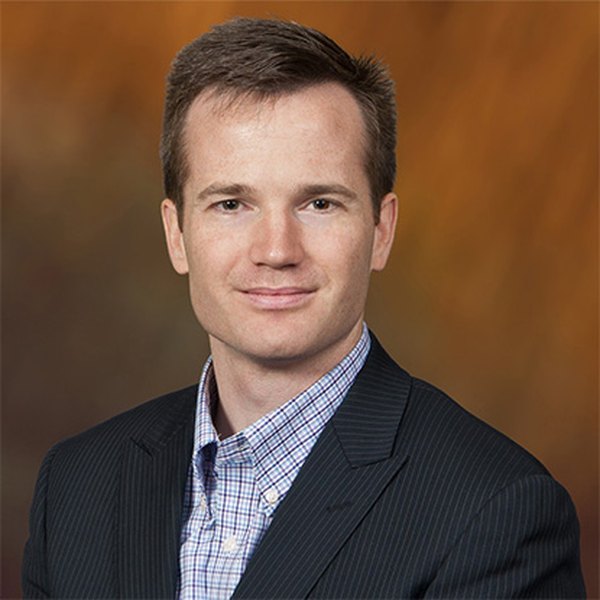
Tim Olsen
Associate Professor of Management Information Systems
School of Business Administration, Gonzaga University
Tim teaches analytics, and does research on XBRL, large language models, semantic modeling, and implications of digital work platforms.
In 2021 he was a US Fulbright Scholar in Malaysia.
Where the data comes from
Every figure on this site originates in a company’s own XBRL exhibit filed with the U.S. Securities and Exchange Commission, by way of the SEC’s Financial Statement and Notes data sets. Nothing is estimated, and nothing is rekeyed by hand.
The work is in the assembly: taking the row structure from a company’s most recent annual report, filling it back through every prior filing, following the concept when a filer retags a line, resolving restatements to the latest reported figure, and keeping the segment detail that standardised databases usually flatten. Each workbook links every period column back to the filing it came from, and carries a Data (long) tab with the XBRL tag and accession number behind every value, so any number can be checked against EDGAR.
Found something that looks wrong? That is the most useful email you can send: olsent@gonzaga.edu.